RAG vs Fine-Tuning: Which Does Your AI Project Actually Need?
Choose between prompting, RAG and fine-tuning by diagnosing missing information versus inconsistent behavior, with examples and a practical evaluation plan.
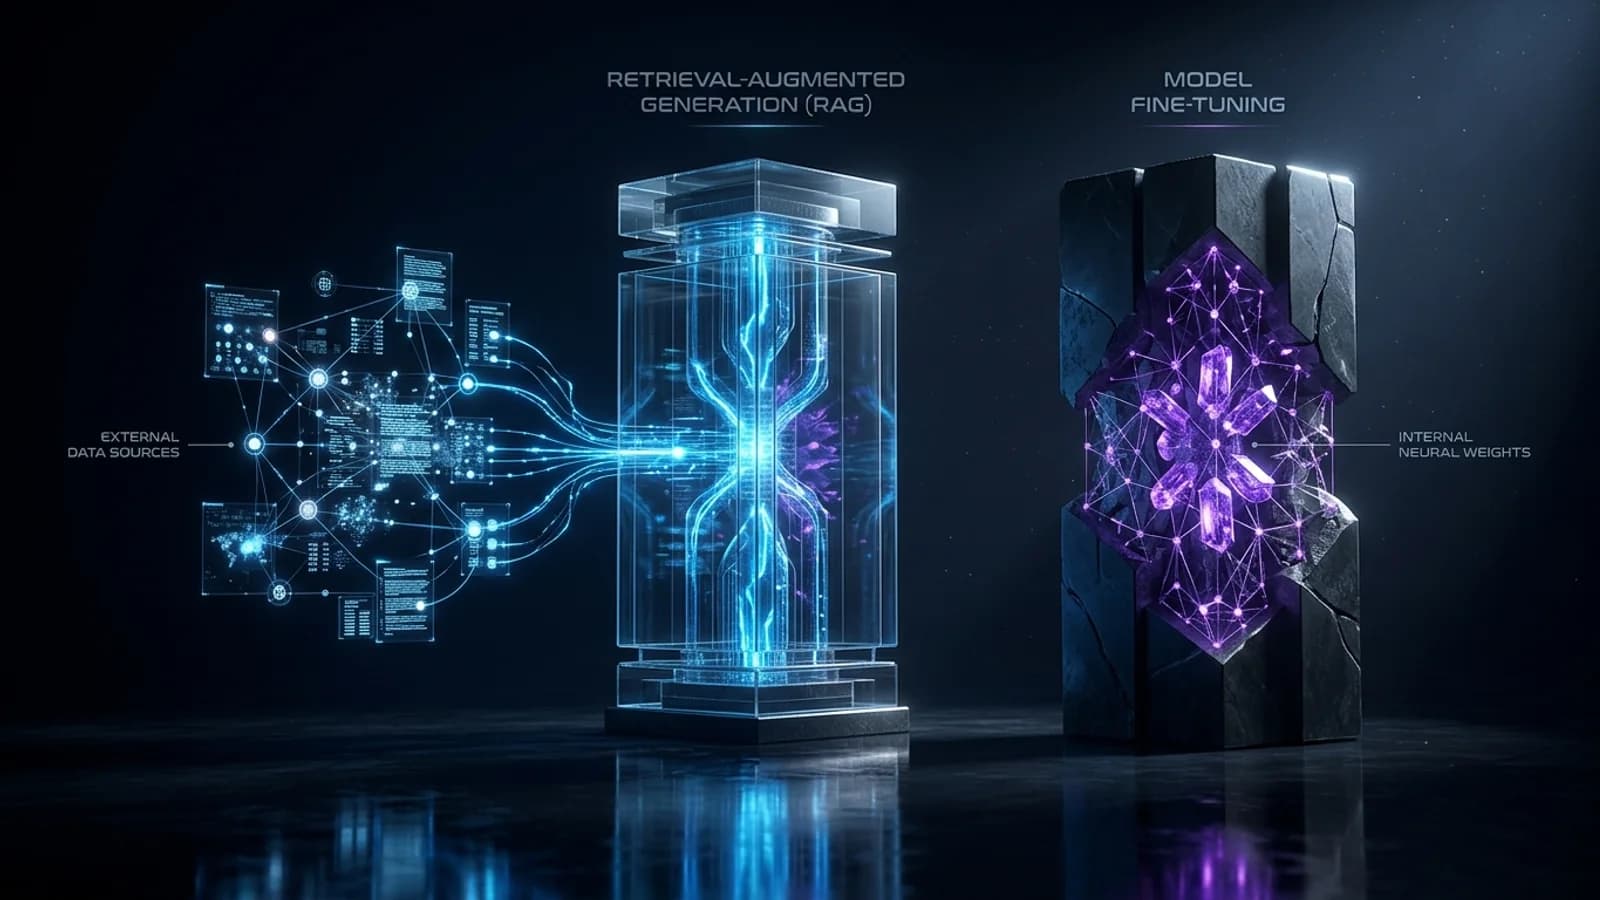
Executive Summary · In 30 Seconds
- RAG supplies information at answer time; fine-tuning changes model behavior through additional training.
- Start with examples of actual failures rather than selecting an architecture from a feature list.
- Fresh documents and traceable evidence usually point toward retrieval; repeated task-specific behavior may justify tuning.
- Evaluate retrieved evidence separately from the final answer so you can locate the failure.
On this page
Start with RAG when the model needs access to relevant information. Consider fine-tuning when you have a repeatable behavior problem and suitable training examples. Neither choice makes sense until you know how the current system fails.
A support assistant that cannot find the current refund policy has a different problem from a classifier that keeps assigning the wrong category to a ticket. Calling both problems “the model needs our data” makes it easy to choose the wrong solution.
This guide is a decision framework for a small project. The examples are illustrative, not measured results from a deployed system. For the mechanics of retrieval, read RAG explained first.
What each approach changes
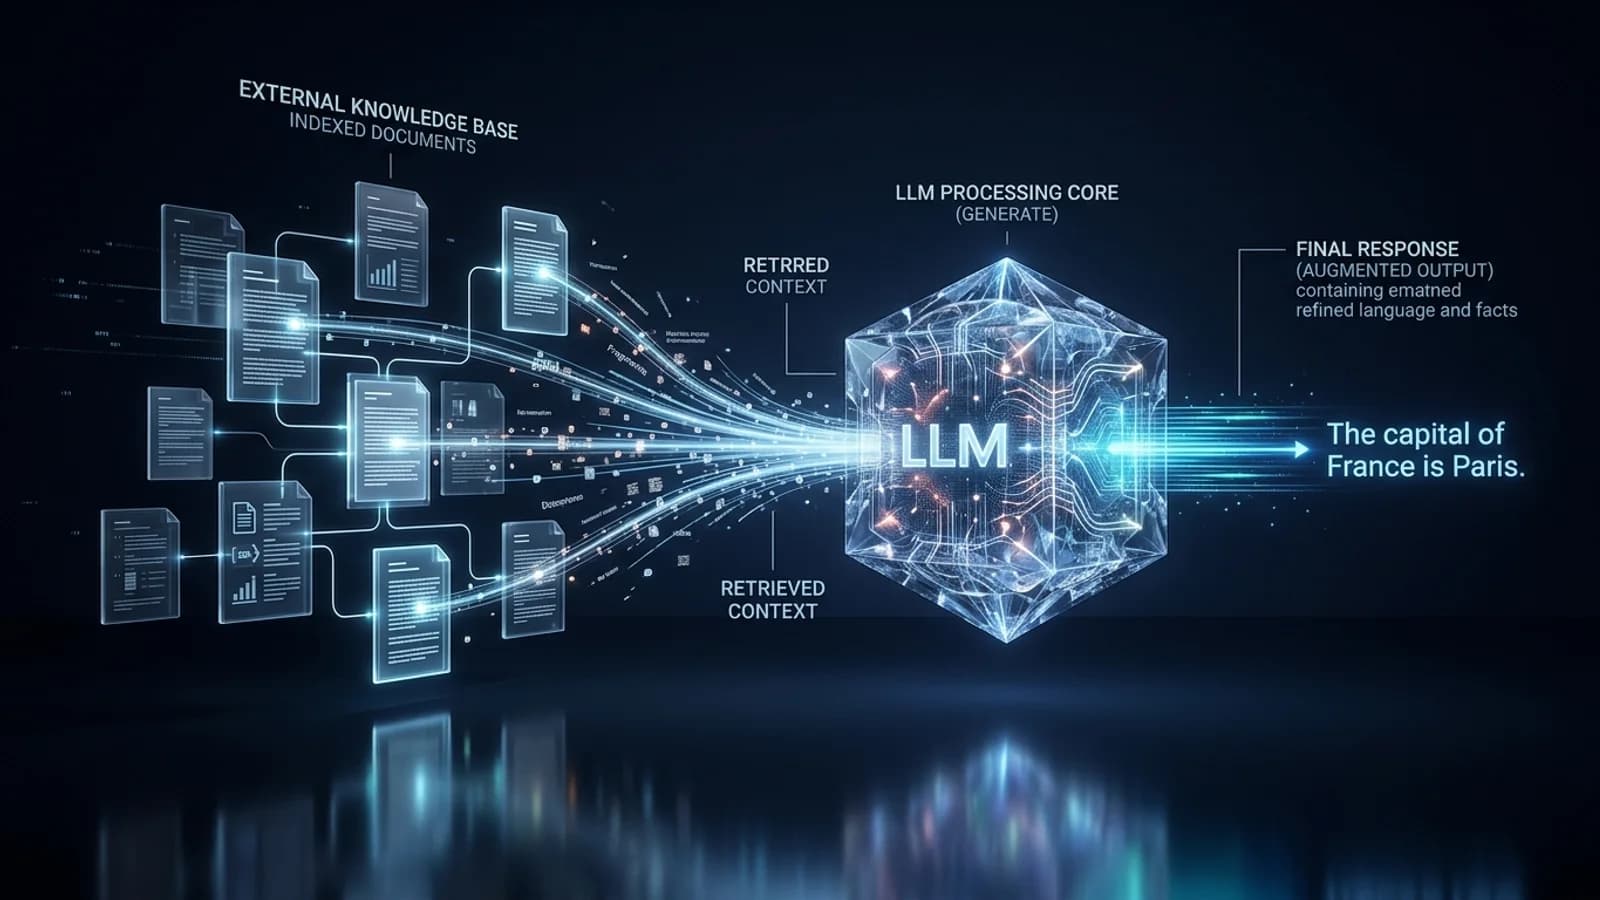
Prompting supplies instructions and examples in the request. RAG retrieves relevant external material and includes it in the model's context. Fine-tuning adds a training stage that updates model parameters using suitable examples.
Google Cloud's overview of fine-tuning distinguishes parameter changes from the external context supplied by RAG. That distinction is more useful than treating the two approaches as competing brands of “smarter AI.”
| Approach | A useful starting case | What it does not guarantee |
|---|---|---|
| Better prompts and examples | Instructions are ambiguous or inconsistent | Correct facts or reliable behavior in every case |
| RAG | Answers need current documents and inspectable evidence | Retrieval of the right passage or correct interpretation |
| Fine-tuning | A defined task needs more consistent specialized behavior | A current, exact copy of a changing knowledge base |
| Both | Current evidence and specialized response behavior are independently needed | A benefit large enough to justify both systems |
Diagnose the failure before choosing the architecture
Collect a small set of realistic requests and write down what a good answer would contain. For each failure, ask whether the model was given the information and instructions it needed.
Consider three examples:
A refund answer uses last year's policy. First check which policy reached the model. If the application retrieved the obsolete document, training the response model does not remove that document from the retrieval index.
A ticket classifier uses categories outside the allowed list. Check the category definitions, examples and output validation. If a clear prompt and examples still fail consistently across a representative evaluation, tuning may be worth investigating.
An answer quotes the correct policy but draws the wrong conclusion. Retrieval succeeded at finding evidence, but the response still failed. Inspect the prompt, task difficulty and model capability before assuming that more documents will help.
This diagnosis prevents you from fixing a behavior problem with a larger search index, or a missing-document problem with additional training.
When retrieval is the stronger starting point
Evaluate RAG when source material changes regularly, the answer needs identifiable evidence, or different users are entitled to different documents. Google's guide to using data with LLMs discusses retrieval for current and private data, along with combining it with tuning.
A useful first version can be narrow: one document collection, one type of question and a visible citation. Do not connect every company system before checking whether retrieval can answer ten representative questions from one well-maintained collection.
Keep an “answer not found” case in the evaluation. If the source contains no return deadline, the system should not manufacture one just because a customer asks confidently.
When fine-tuning deserves an experiment
Fine-tuning is worth evaluating when you can describe the target behavior, provide suitable examples, and measure improvement on separate examples. Consistent labeling or a specialized response style can be candidate tasks.
Before beginning, answer four questions:
- What observable failure should improve?
- How will you obtain accurate and representative training examples?
- Which examples will be kept out of training for evaluation?
- What result would justify maintaining a tuned model?
“It should sound more like us” is not yet a complete evaluation criterion. A rubric might instead check terminology, required sections, prohibited unsupported claims and whether the response follows a specific style example.
If your examples disagree with each other, resolve that disagreement before training. Otherwise you cannot tell whether the model or the target behavior is inconsistent.
A small evaluation you can run before committing
Build a worksheet of roughly 20 representative requests as an initial diagnostic set. This suggested size is a starting point for investigation, not a statistically sufficient production benchmark.
Include ordinary requests, missing-information cases and difficult edge cases. For a retrieval prototype, record the evidence separately:
| Field | What to write down |
|---|---|
| Request | The actual user question |
| Expected evidence | Document and passage needed to answer |
| Retrieved evidence | What the system actually supplied |
| Answer assessment | Correct, incomplete, unsupported or incorrect |
| Next change | Source cleanup, retrieval adjustment, prompt change or model experiment |
Run the same set against the current prompt-only baseline and the proposed change. Keep the cases fixed for that comparison. Expand the evaluation before making a production decision, especially when real usage includes a wider range of languages, document types or tasks.
Compare operating cost, not just the first invoice
For retrieval, account for document ingestion, indexing, query processing, context passed to the model and source maintenance. For tuning, account for data preparation, training, inference and repeated evaluation when requirements change.
Also record response time and how much human correction is needed. A technically cheaper answer that takes longer to check may not be cheaper for the workflow.
There is no universal winner. Use your own request volume, document-update frequency and observed failure rate rather than a generic percentage from someone else's project.
A sensible first decision
Improve the baseline prompt and inspect real failures. Add retrieval if relevant evidence is missing. Investigate tuning if a defined behavior remains inconsistent and you have the data to test that hypothesis. Combine them only when each solves a demonstrated problem.
Google explicitly describes these techniques as potentially complementary in its LLM specialization design pattern. Whatever you choose, keep checking unsupported answers: access to documents or additional training does not make factual verification unnecessary.
Common Questions & Practical Answers
Yes. Retrieval can provide current source material while a tuned model follows a specialized task or response style. Evaluate the contribution of each component before accepting the additional complexity.
Practical guides published by Lucivo, developed with AI assistance and references to official documentation. Examples are illustrative unless a guide explicitly documents a hands-on test. Check the linked sources for current product details.
Related articles
How to Run AI Locally With Ollama: A Beginner's Setup Guide
What Is an AI Agent, Really?
RAG Explained Without the Jargon
The Weekly Breakdown
High signal AI & software stories.
Direct to your inbox. No hype.
Independent analysis of AI models, developer tools, and computing architectures. Delivered every Sunday morning. 100% free.